Immich on 6 GB RAM: import 500 photos with ML on and off
Tested on Immich 3.3.5
Test result
On a 4 vCPU, 6 GB VM, Immich 3.3.5 cleared every job queue for 500 generated photos in 321 s with machine learning enabled and 95 s with it disabled (one run each; an earlier run of the same script gave 349 s and 101 s). The four containers peaked at 3,855 MiB with ML and 2,760 MiB without, so the 6 GB minimum in the docs was enough for this run; the images were abstract shapes, so real photos may cost more.
Immich is the heaviest app in the series so far, and the machine-learning container is the reason. This test imported the same 500 generated images twice into fresh installs, once with machine learning enabled and once with machineLearning.enabled set to false, and watched the queues and the memory of each container.
What the docs ask for
The requirements page says minimum 6 GB of RAM (8 GB recommended) and a minimum of 2 CPU cores (4 recommended). It says systems with only 4 GB can run Immich with machine learning disabled, that the Postgres data should sit on local SSD storage, and that with Docker resource limits Postgres needs at least 2 GB. Thumbnails and transcoded video, it says, can add 10 to 20 % to the library size. The VM here had 6 GB and 4 vCPUs, which is the documented RAM minimum and the recommended CPU count.
The config-file page lists a top-level machineLearning.enabled flag, which is what the second run set through PUT /api/system-config. The system settings page also describes turning off individual features such as smart search or facial recognition.
What was imported
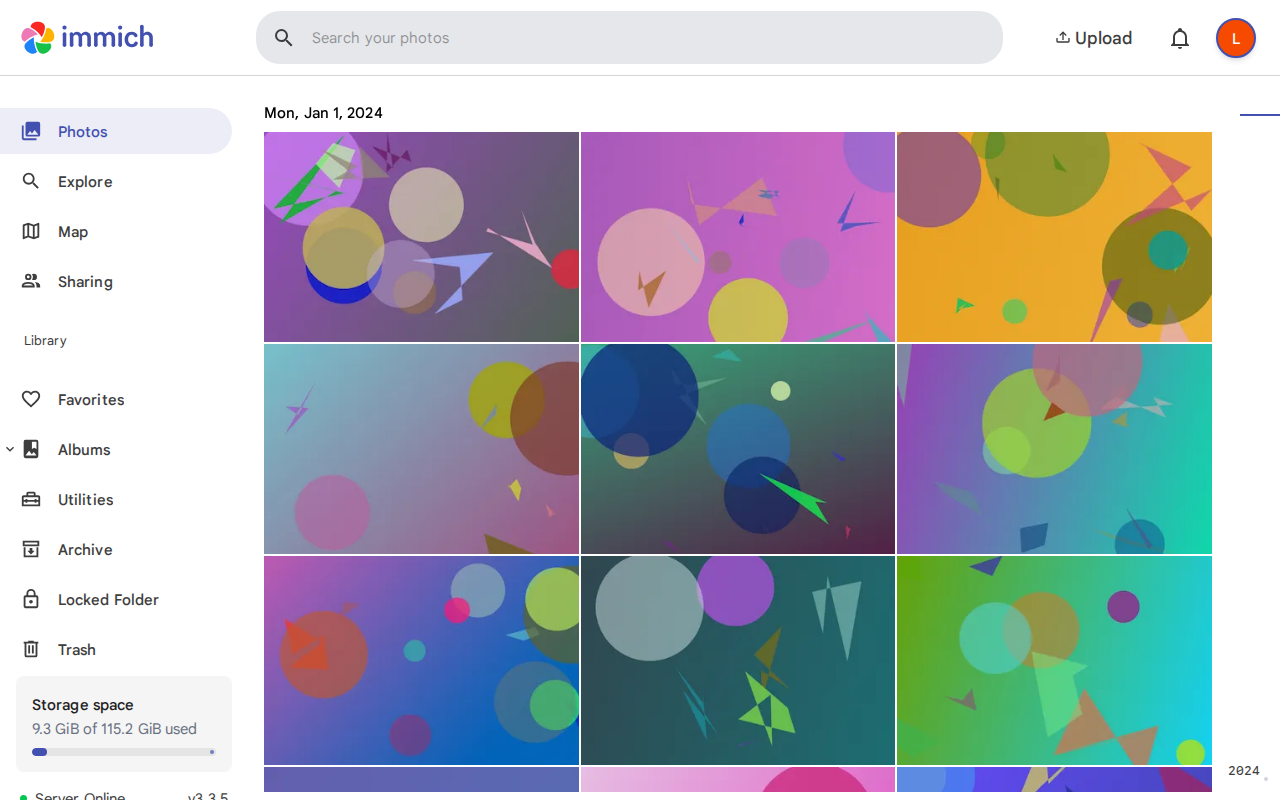
500 JPEGs (plus 10 warm-up images), 3000x2000 pixels, about 0.3 MB each, 153.7 MB for all 510. They are generated gradients with random shapes and noise (gen_images.py), uploaded through POST /api/assets with 4 parallel workers. They contain no faces, objects or scenes, so face detection and the smart search model had no real subject. The ML time here may therefore understate the cost of real photos (the test did not measure that), and it says nothing about recognition quality. The upload itself took 15.3 s with ML on and 12.9 s with it off.
Results
| Measurement | Machine learning on | Machine learning off |
|---|---|---|
| Warm-up: 10 images, time until the queues were empty (s) | 23 | 9 |
| Upload of 500 images, 4 parallel workers (s) | 15.3 | 12.9 |
| Time from upload start until every queue was empty (s) | 321 | 95 |
| of which after the last upload finished (s) | 306 | 82 |
| per image, from upload start (s) | 0.64 | 0.19 |
| Upload errors | 0 | 0 |
| Photos counted by the server | 510 | 510 |
| Smart-search query `green circle`: assets returned (HTTP status) | 510 (200) | None (400) |
| Total RAM, all 4 containers: idle before the upload, median (MiB) | 1954 | 2081 |
| Total RAM while the queues were busy: median / peak sample (MiB) | 3518 / 3855 | 2655 / 2760 |
| Total RAM 30 s to 120 s after the queues emptied, median (MiB) | 2689 | 2468 |
| Total CPU while the queues were busy, mean / peak (% of one vCPU) | 326 / 402 | 344 / 386 |
One run per setting on a 4 vCPU, 6 GB VM (LAB_MEM=6144); ML-on always ran first, ML-off second, in the same VM. The smart-search query ran after the memory sampler had stopped, so it is not in any RAM window. Images are generated abstract pictures (3000x2000 JPEG, about 0.3 MB each) with no faces or objects. docker stats RAM excludes page cache. The ML-on warm-up includes downloading the models.
| Run | Container | Idle before | Peak while busy | Median 30-120 s after |
|---|---|---|---|---|
| Machine learning on | database | 409 | 428 | 429 |
| Machine learning on | immich-machine-learning | 196 | 1507 | 994 |
| Machine learning on | immich-server | 1344 | 1971 | 1260 |
| Machine learning on | redis | 4 | 7 | 6 |
| Machine learning off | database | 392 | 407 | 407 |
| Machine learning off | immich-machine-learning | 208 | 255 | 208 |
| Machine learning off | immich-server | 1476 | 2139 | 1846 |
| Machine learning off | redis | 5 | 7 | 7 |
Samples come from docker stats --no-stream and are about 2 s apart, both while busy and at idle.
| Queue | Machine learning on | Machine learning off |
|---|---|---|
| duplicateDetection | 136 | never busy |
| faceDetection | 203 | never busy |
| metadataExtraction | 17 | 13 |
| ocr | 315 | 29 |
| smartSearch | 181 | never busy |
| storageTemplateMigration | 15 | never busy |
| thumbnailGeneration | 179 | 89 |
From polling GET /api/queues every 2 s (active + waiting + delayed). Queues that were never busy in the poll window are shown as such.
- Time to clear: 321 s with ML (0.64 s per image from upload start) and 95 s without (0.19 s). The OCR queue was the last to finish with ML on, at 315 s; smart search and face detection finished at 181 s and 203 s. With ML off the thumbnail queue was last, at 89 s.
- RAM peaks: the ML container reached 1,507 MiB and the server container 1,971 MiB; all four together peaked at 3,855 MiB, with a median of 3,518 MiB while busy. With ML off the total peaked at 2,760 MiB and the ML container stayed at 255 MiB at most. All peaks are maxima of
docker statssamples about 2 s apart, not 1 s. - RAM after the work, median over the 30 to 120 s after the queues emptied: with ML on the server container held 1,260 MiB and the ML container 994 MiB, 2,689 MiB in total; with ML off the server container held 1,846 MiB and the total was 2,468 MiB. So the server container used more memory after the work with ML off than with ML on, but the ML container’s share made the ML-on total higher. An earlier run of the same script (its raw files were not kept) gave the opposite order of totals (2,490 MiB with ML on, 2,749 MiB with ML off), so this ordering is not stable between runs. The smart-search request ran after the memory sampler had stopped, so the textual model it loads is not in these windows. One run per setting; the test did not look into why.
- The ML container kept its models loaded after the queues emptied (994 MiB median in that window). Its log says the in-memory model cache unloads after 300 s, and the window here was shorter than that, so the memory it frees later was not measured.
- With ML off, a smart-search request returned HTTP 400. With ML on it returned all 510 assets for the query “green circle”, which shows every asset had an embedding but says nothing about how well the results match.
- The models are downloaded on first use: the ML run’s warm-up took 23 s against 9 s with ML off, and the model-cache volume was 2.197 GB afterwards.
- CPU averaged 326 % of one vCPU while busy with ML on and 344 % with it off, so both runs used almost all 4 vCPUs; the ML run simply stayed busy 3.4 times longer.
| Stack | Version | RAM at idle | CPU at idle | Images on disk | Ready after |
|---|---|---|---|---|---|
| Immich | 3.3.5 | 0.40% | 4706.9 MB | 17 s |
The stack table’s idle figure comes from a separate first-run measurement and is lower than the idle median here (1,954 MiB before the upload with ML on, 2,081 MiB with ML off). The two were not reconciled.
Steps
docker compose up -d
python3 bench.py ml-on 1 500 ~/imgs ~/out    # admin sign-up, API key, upload, poll GET /api/queues
python3 bench.py ml-off 0 500 ~/imgs ~/out # same on a fresh install with machineLearning.enabled=falseThis file uses the public test value lab-only-not-a-secret. Replace every instance with your own secret before you run it.
services:
  immich-server:
    image: ghcr.io/immich-app/immich-server:v3.3.5
    restart: unless-stopped
    volumes:
      - ./library:/data
      - /etc/localtime:/etc/localtime:ro
    environment: &env
      DB_PASSWORD: lab-only-not-a-secret
      DB_USERNAME: postgres
      DB_DATABASE_NAME: immich
    ports:
      - "127.0.0.1:8080:2283"
    depends_on: [redis, database]
  immich-machine-learning:
    image: ghcr.io/immich-app/immich-machine-learning:v3.3.5
    restart: unless-stopped
    volumes:
      - model-cache:/cache
    environment: *env
  redis:
    image: docker.io/valkey/valkey:9
    restart: unless-stopped
  database:
    image: ghcr.io/immich-app/postgres:14-vectorchord0.4.3-pgvectors0.2.0
    restart: unless-stopped
    environment:
      POSTGRES_PASSWORD: lab-only-not-a-secret
      POSTGRES_USER: postgres
      POSTGRES_DB: immich
      POSTGRES_INITDB_ARGS: --data-checksums
    volumes:
      - ./postgres:/var/lib/postgresql/data
    shm_size: 128mb
volumes:
model-cache:This file uses the public test value lab-only-not-a-secret. Replace every instance with your own secret before you run it.
Show the full file
#!/usr/bin/env python3
"""Runs in the VM. bench.py <label> <ml:1|0> <n_images> <imgdir> <outdir>
Creates the admin, an API key, optionally disables machine learning through PUT /api/system-config, uploads 10 warm-up images
(not counted, they pull the ML models in on the ML run), waits for the queues, then uploads n images with 4 workers and polls
GET /api/queues every 2 s until every queue has been empty (active+waiting+delayed = 0) for 3 polls in a row.
The smart-search request is NOT made here (it loads the textual CLIP model and would add to the post-work memory window); run.sh runs search.py after the memory sampler has stopped."""
import sys, os, json, time, threading, urllib.request, urllib.error, glob, uuid
label, ml, n, imgdir, outdir = sys.argv[1], int(sys.argv[2]), int(sys.argv[3]), sys.argv[4], sys.argv[5]
U = "http://127.0.0.1:8080/api"; os.makedirs(outdir, exist_ok=True)
def call(method, path, body=None, headers=None, raw=None):
    h = dict(headers or {}); data = raw
    if body is not None: data = json.dumps(body).encode(); h["Content-Type"] = "application/json"
    r = urllib.request.Request(U + path, data=data, method=method, headers=h)
    try:
        with urllib.request.urlopen(r, timeout=120) as x: t = x.read(); return x.status, (json.loads(t) if t else None)
    except urllib.error.HTTPError as e: return e.code, e.read().decode()[:300]
st, r = call("POST", "/auth/admin-sign-up", {"email": "admin@lab.invalid", "name": "Lab Admin", "password": "lab-only-not-a-secret"}); assert st in (200, 201), (st, r)
st, r = call("POST", "/auth/login", {"email": "admin@lab.invalid", "password": "lab-only-not-a-secret"}); tok = r["accessToken"]
st, r = call("POST", "/api-keys", {"name": "bench", "permissions": ["all"]}, {"Authorization": "Bearer " + tok}); KEY = {"x-api-key": r["secret"]}
call("PUT", "/users/me/onboarding", {"isOnboarded": True}, KEY)
st, cfg = call("GET", "/system-config", headers=KEY)
cfg["machineLearning"]["enabled"] = bool(ml); st, r = call("PUT", "/system-config", cfg, KEY); assert st == 200, (st, r)
st, cfg = call("GET", "/system-config", headers=KEY); print("machineLearning.enabled =", cfg["machineLearning"]["enabled"], flush=True)
def upload(path, i):
    b = uuid.uuid4().hex; name = os.path.basename(path); data = open(path, "rb").read()
    def f(k, v): return f'--{b}\r\nContent-Disposition: form-data; name="{k}"\r\n\r\n{v}\r\n'.encode()
    body = (f("deviceAssetId", f"{name}-{label}") + f("deviceId", "labgen") + f("fileCreatedAt", "2024-01-01T00:00:00.000Z") + f("fileModifiedAt", "2024-01-01T00:00:00.000Z")
            + f'--{b}\r\nContent-Disposition: form-data; name="assetData"; filename="{name}"\r\nContent-Type: image/jpeg\r\n\r\n'.encode() + data + f"\r\n--{b}--\r\n".encode())
    return call("POST", "/assets", headers={**KEY, "Content-Type": f"multipart/form-data; boundary={b}"}, raw=body)[0]
def busy():
    st, qs = call("GET", "/queues", headers=KEY); assert st == 200, (st, qs)
    return {q["name"]: q["statistics"]["active"] + q["statistics"]["waiting"] + q["statistics"]["delayed"] for q in qs}
def wait_idle(csv, quiet=3, timeout=7200):
    ok = 0; t0 = time.time(); first = True; clear = {}
    while time.time() - t0 < timeout:
        b = busy(); now = time.time()
        if first and csv is not None: csv.write("epoch," + ",".join(sorted(b)) + "\n"); first = False
        if csv is not None: csv.write(f"{now:.2f}," + ",".join(str(b[k]) for k in sorted(b)) + "\n"); csv.flush()
        ok = ok + 1 if sum(b.values()) == 0 else 0
        if ok >= quiet: return now
        time.sleep(2)
    raise SystemExit("queues never cleared")
files = sorted(glob.glob(f"{imgdir}/*.jpg")); assert len(files) >= n + 10, len(files)
res = {"label": label, "ml_enabled": bool(ml), "n": n}
t = time.time(); errs = sum(1 for i, p in enumerate(files[:10]) if upload(p, i) not in (200, 201))
w_end = wait_idle(None); res["warmup"] = {"images": 10, "errors": errs, "secs": w_end - t}; print("warmup", res["warmup"], flush=True)
open(f"{outdir}/MARK_warm_done", "w").write(str(time.time()))
csv = open(f"{outdir}/{label}-queues.csv", "w"); batch = files[10:10 + n]; it = iter(enumerate(batch)); lk = threading.Lock(); bad = [0]
def worker():
    while True:
        with lk: x = next(it, None)
        if x is None: return
        if upload(x[1], x[0]) not in (200, 201):
            with lk: bad[0] += 1
t0 = time.time(); th = [threading.Thread(target=worker) for _ in range(4)]; [x.start() for x in th]
poll = threading.Thread(target=lambda: None)
[x.join() for x in th]; t1 = time.time(); res["upload"] = {"t_start": t0, "t_end": t1, "secs": t1 - t0, "errors": bad[0]}; print("upload", res["upload"], flush=True)
t2 = wait_idle(csv); res["queues_clear"] = {"t_end": t2, "secs_from_upload_start": t2 - t0, "secs_from_upload_end": t2 - t1}; print("clear", res["queues_clear"], flush=True)
st, stats = call("GET", "/server/statistics", headers=KEY); res["server_statistics"] = stats
json.dump(res, open(f"{outdir}/{label}-bench.json", "w"), indent=1); print(json.dumps(res)[:600])
What went wrong
In this version GET /api/queues reported completed as 0 even after jobs had run, so “finished” is defined as every queue holding no active, waiting or delayed jobs for three consecutive 2 s polls, and was confirmed afterwards by the smart-search count and the server’s photo count (510 in both runs).
What this test did not cover
Sources and how this was made
Show the full file
#!/usr/bin/env bash
# immich: Immich 3.3.5, 500 generated JPEGs (3000x2000) through POST /api/assets, once with machine learning enabled and once with
# machineLearning.enabled=false (PUT /api/system-config). Time until every job queue is empty, RAM per container, RAM afterwards.
set -uo pipefail
export LAB_MEM=6144
source "$(dirname "$0")/../_e/lib.sh"
T=immich; D="$ROOT/lab/tests/$T"; OUT="$ROOT/evidence/tests/$T"; RAW="$OUT/raw"; N=500
rm -rf "$OUT"; mkdir -p "$RAW" "$ROOT/public/shots/$T"
start_vm "${VMP:-e}-$T" || exit 1
collect_env "$OUT"
gx 'sudo apt-get install -y -qq python3-pil python3-numpy >/dev/null 2>&1; mkdir -p ~/im'
vm scp-to "$D/gen_images.py" g.py; vm scp-to "$D/bench.py" bench.py; vm scp-to "$D/search.py" search.py; vm scp-to "$ROOT/lab/tests/_e/sampler.py" sampler.py; vm scp-to "$ROOT/lab/stacks/immich/compose.yml" im/compose.yml
S=$(now_ms); gx "python3 g.py ~/imgs $((N + 10))" | tee "$RAW/dataset.txt"; echo "gen_ms=$(( $(now_ms) - S ))" >> "$RAW/dataset.txt"
gx 'cd im && docker compose pull -q 2>&1 | tail -1; docker images --format "{{.Repository}}:{{.Tag}} {{.ID}}" | sort' > "$RAW/images.txt"
for RUN in ml-on ml-off; do
  ML=1; [ $RUN = ml-off ] && ML=0
  echo "=== $RUN"
  gx 'cd im && docker compose down -v >/dev/null 2>&1; sudo rm -rf library postgres ~/out; docker compose up -d >/dev/null 2>&1; for i in $(seq 1 120); do curl -fs http://127.0.0.1:8080/api/server/ping >/dev/null && exit 0; sleep 3; done; exit 1'
  gx 'sleep 60'
  gx "timeout 40 python3 sampler.py /tmp/idle0.csv 2 || true; cat /tmp/idle0.csv" > "$RAW/$RUN-mem-idle-before.csv"
  gx 'nohup python3 sampler.py /tmp/run.csv 1 >/dev/null 2>&1 & echo $! > /tmp/sampler.pid'
  gx "python3 bench.py $RUN $ML $N ~/imgs ~/out" 2>&1 | tee "$RAW/$RUN-bench.log" | cut -c1-200
  gx 'sleep 120; kill $(cat /tmp/sampler.pid); sleep 2; cat /tmp/run.csv' > "$RAW/$RUN-mem-run.csv"
gx "python3 search.py $RUN ~/out" > "$RAW/$RUN-search.log" 2>&1; gx "cat ~/out/$RUN-search.json" > "$RAW/$RUN-search.json"
  gx "cat ~/out/$RUN-bench.json" > "$RAW/$RUN-bench.json"; gx "cat ~/out/$RUN-queues.csv" > "$RAW/$RUN-queues.csv"; gx 'cat ~/out/MARK_warm_done' > "$RAW/$RUN-warm-done-epoch.txt"
  gx 'cd im && sudo du -sb library postgres | cat; docker system df -v 2>/dev/null | grep -i "model-cache\|im_"' > "$RAW/$RUN-disk.txt" 2>&1
  gx 'cd im && docker compose logs --no-color immich-machine-learning 2>&1 | grep -ic "download\|loading\|Loaded" ; docker compose logs --no-color immich-machine-learning 2>&1 | grep -i "loading\|loaded" | cut -c1-200 | head -12' > "$RAW/$RUN-ml-log.txt" 2>&1
  if [ $RUN = ml-on ]; then
    tunnel 18092 8080
    ( cd "$D" && node shot.mjs http://127.0.0.1:18092 "$ROOT/public/shots/$T/timeline.png" ) > "$RAW/shot.txt" 2>&1
    untunnel
  fi
done
python3 "$D/summarize.py" "$RAW" "$OUT"How this page was made: the commands above were run by an AI agent on the test box on November 1, 2026, and the same agent drafted this text from the saved output. The site's owner reviewed the site before publication. Test method and editorial policy explain how results are checked, and what is not. Spotted an error? Tell us.